swarm-board V0.2static demo

CCT SUMMARIZER / V0.2

Training on Nebius Token Factory

How the three summary schemas work, how the state-graph LoRA was trained, and how it was evaluated on held-out turns. No paid API or training jobs run from this dashboard.

The pipeline

Stage 1 · Prose v1

Hourly bullets and message labels

A small model (Qwen3-30B-A3B) reads every agent message once. Per agent and hour it writes four bullet lists (started, finished, blocked, key decisions) and tags each message with intent, role, blocker and urgency.

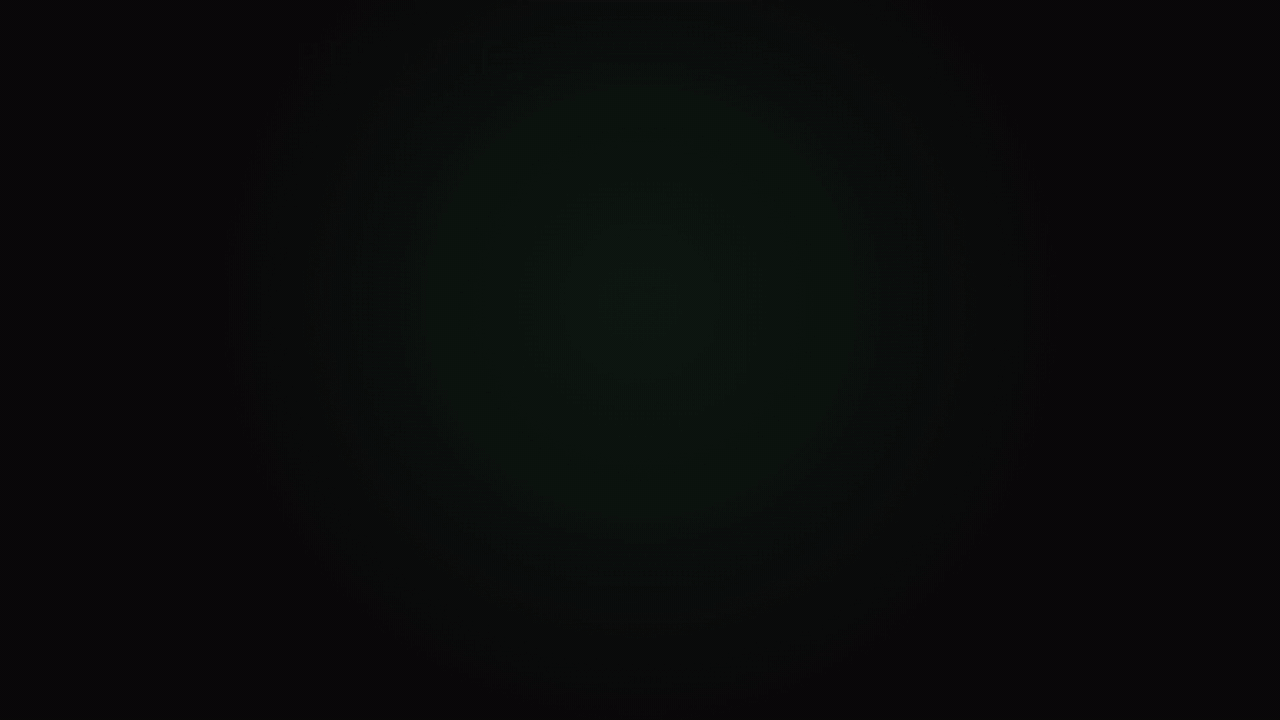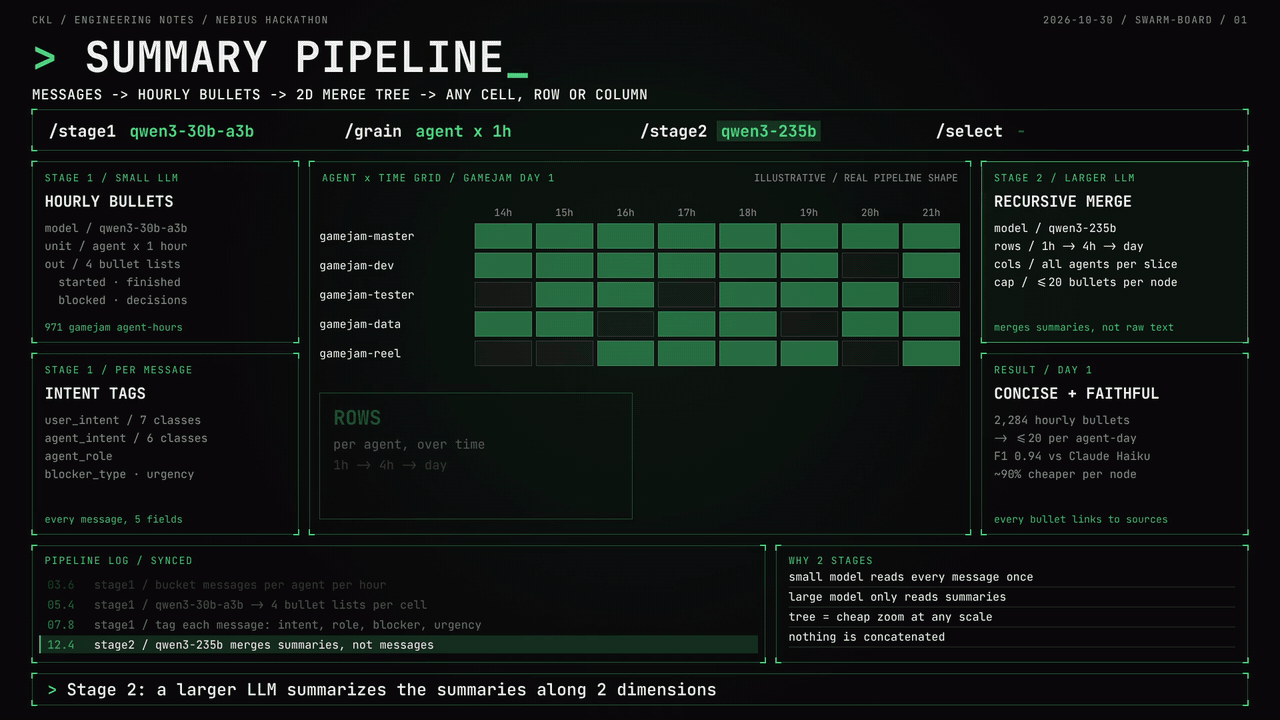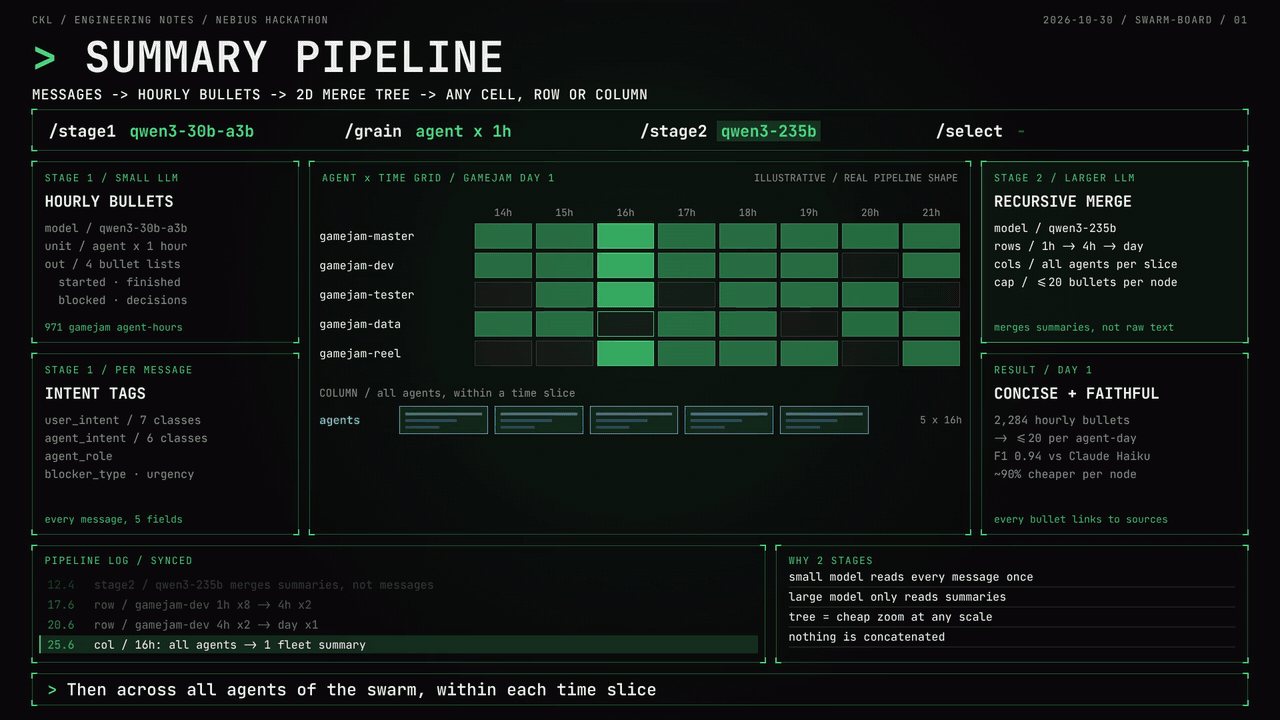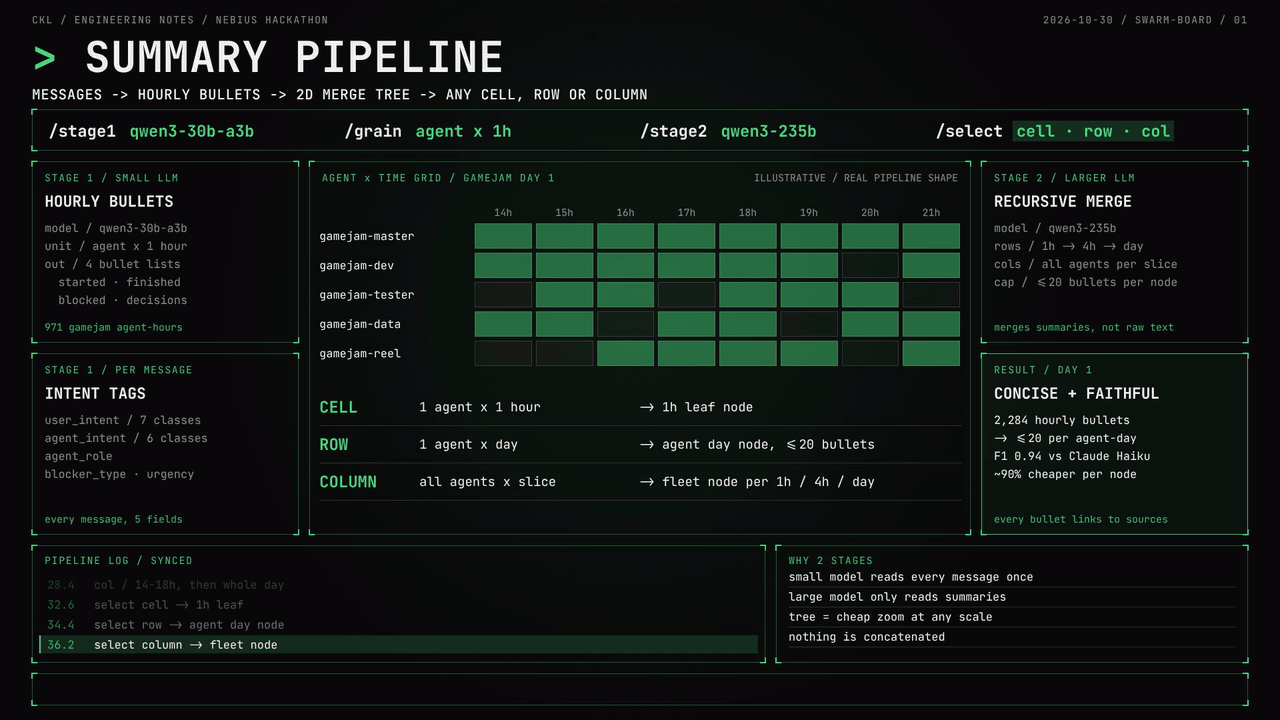
Summary pipeline: messages to hourly bullets to a 2D merge tree

Stage 2 · Prose v2

2D merge tree

A larger model (Qwen3-235B) merges the hourly bullets up two axes: one agent over time (1h, 4h, day) and all agents in one time bucket (1h, 4h, day). Any cell, row or column of the timeline is answered by one merged node, with every bullet linked to its sources.

State graph · v0.3 lean

Project state, turn by turn

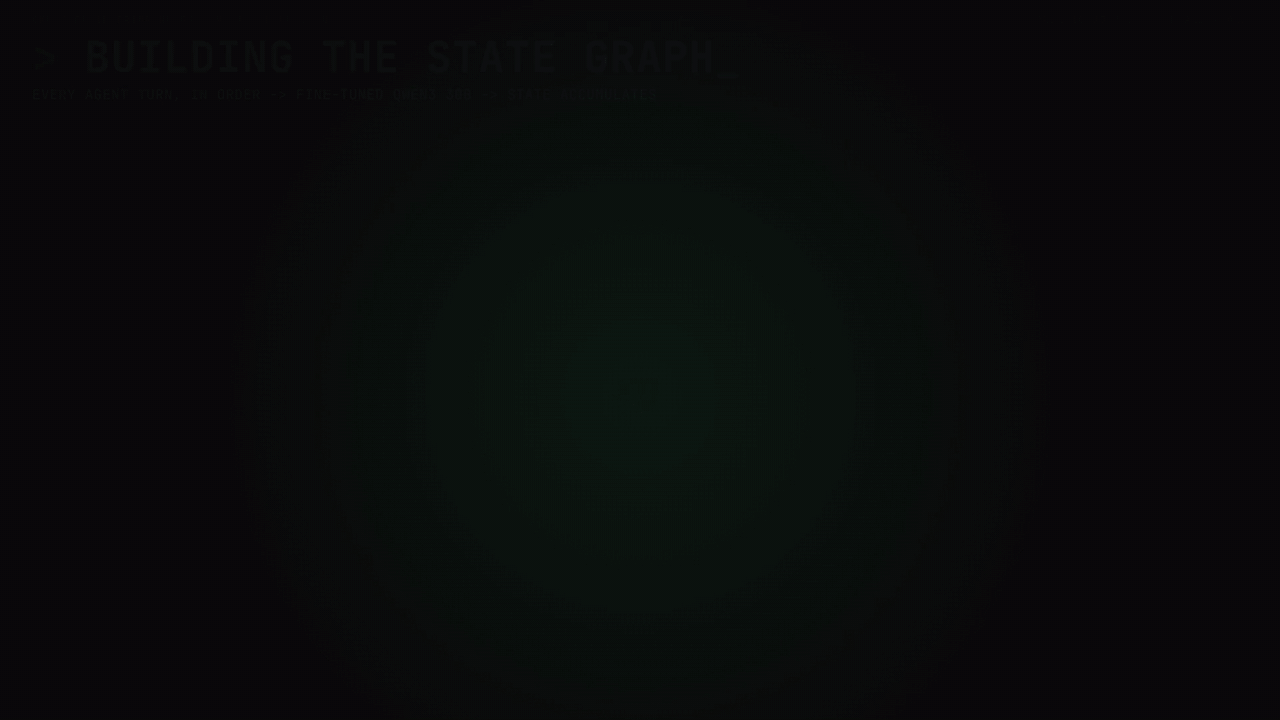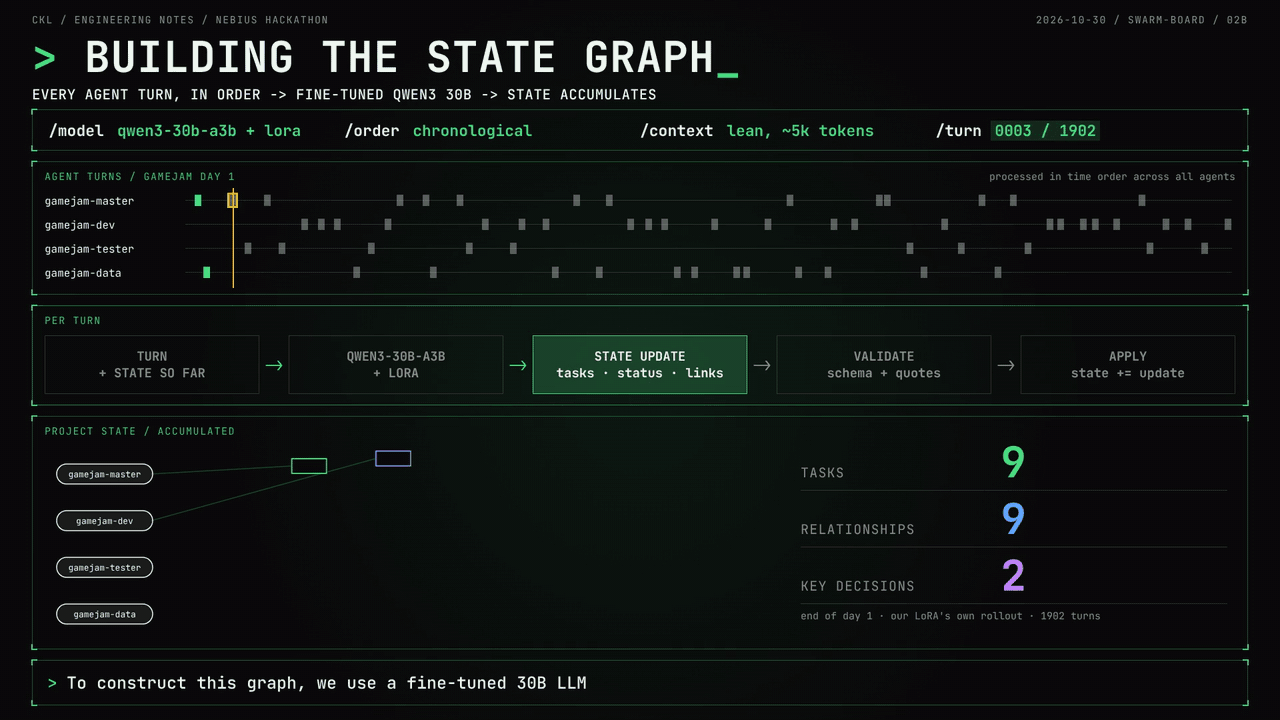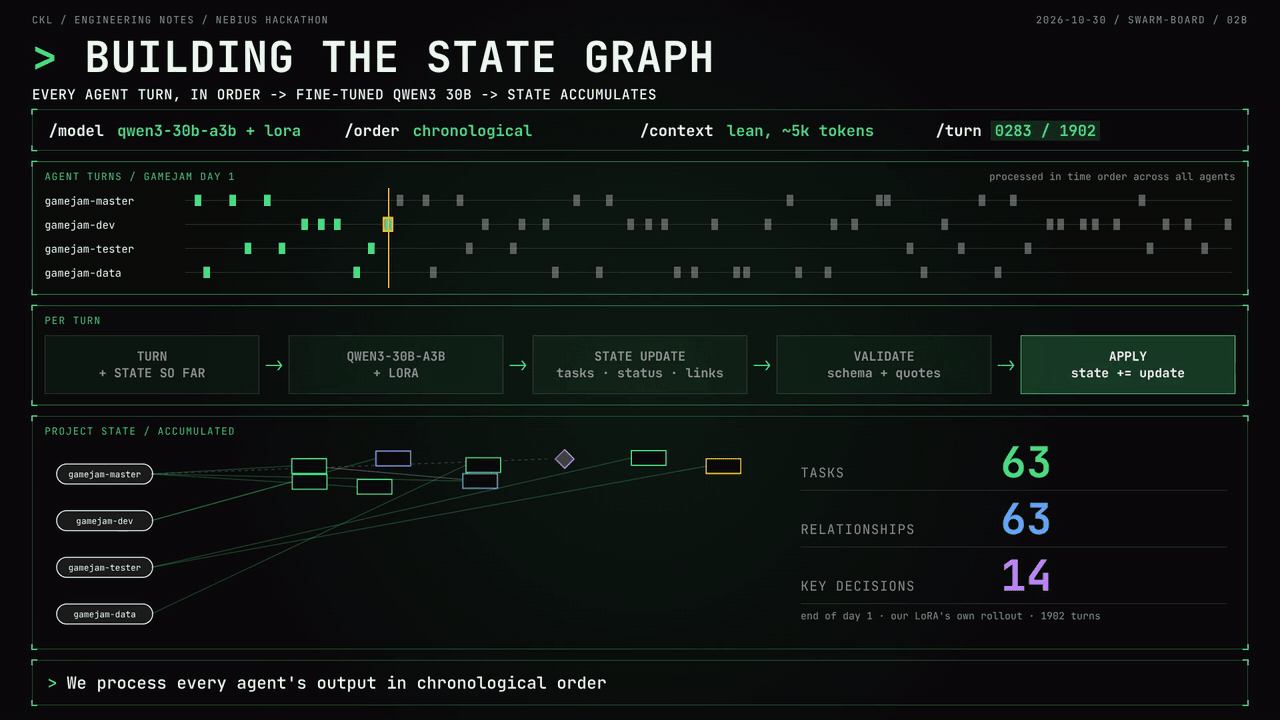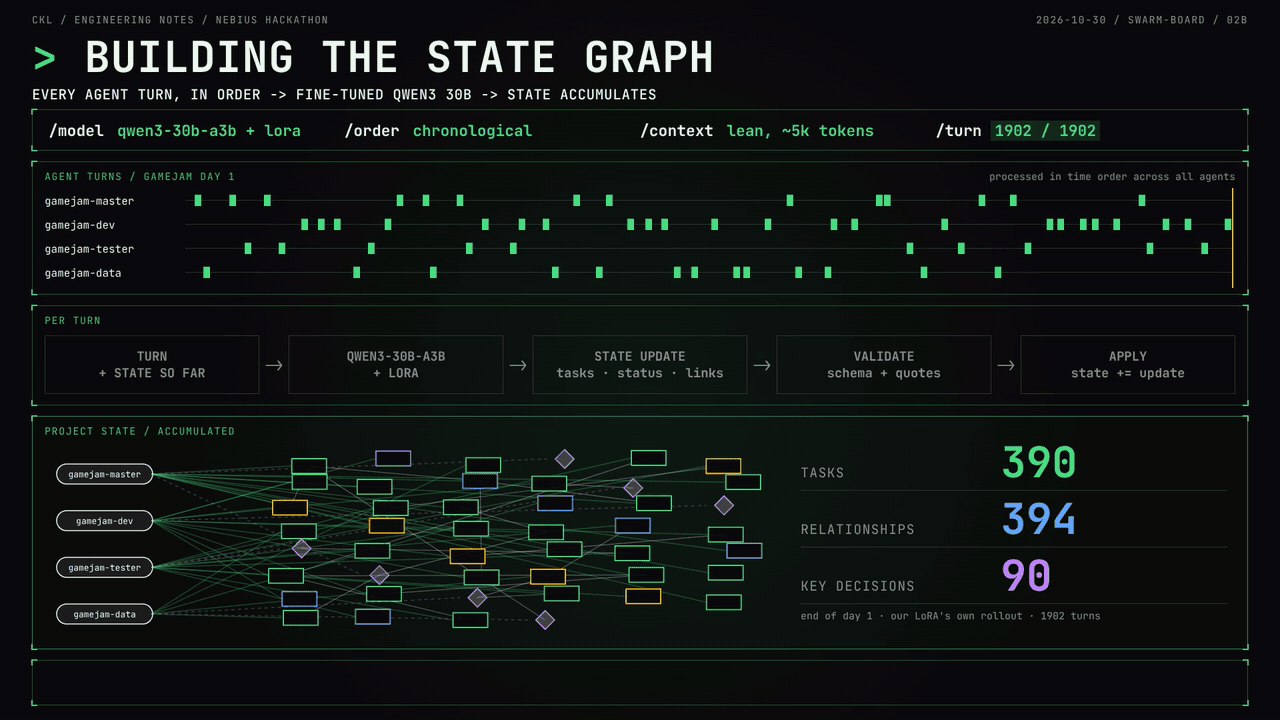
For every agent turn, in order, a fine-tuned Qwen3-30B-A3B LoRA emits a JSON patch (tasks, status, relationships, key decisions). The patch is validated against the schema and quotes, then applied, so the project graph accumulates across the whole fleet.

Building the state graph turn by turn

Training the state-graph model

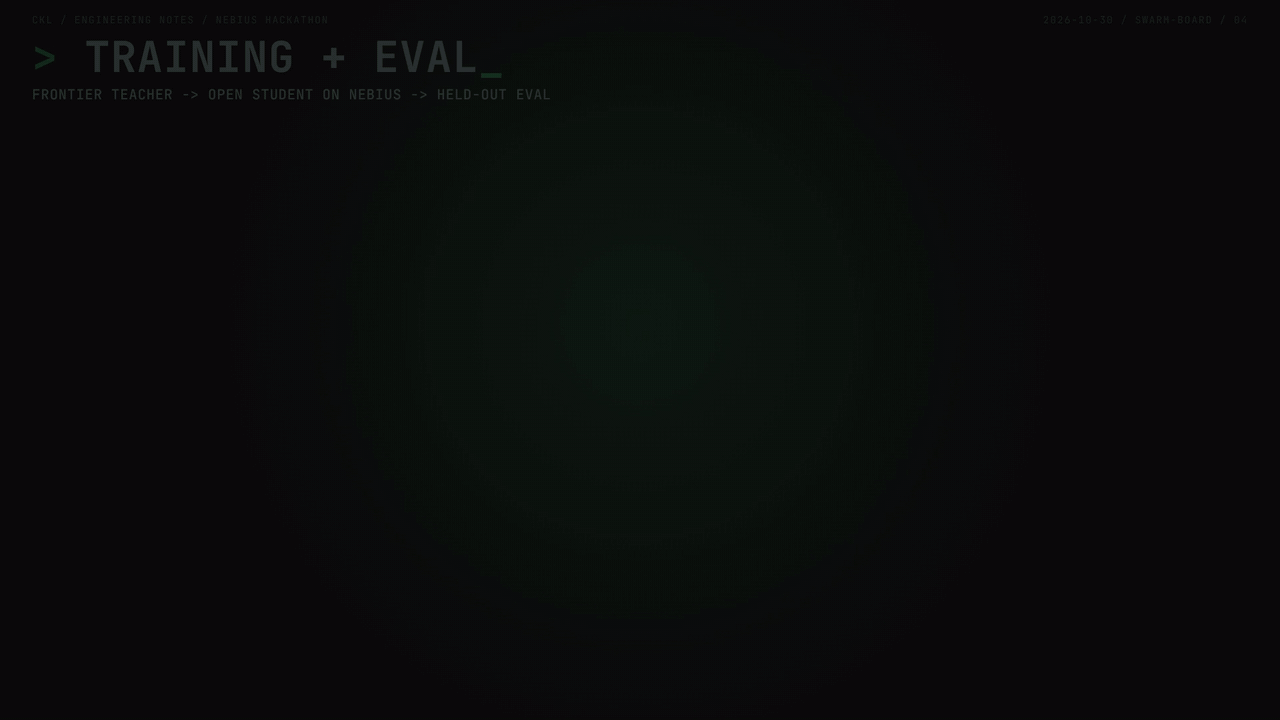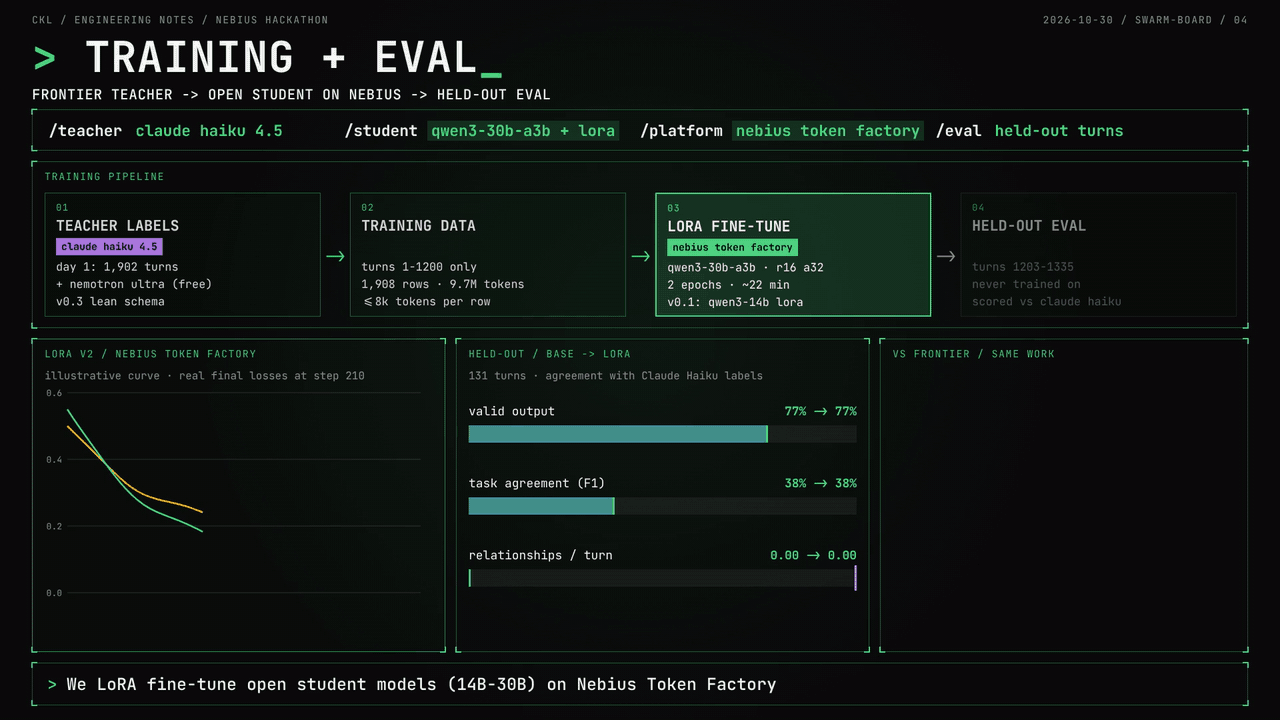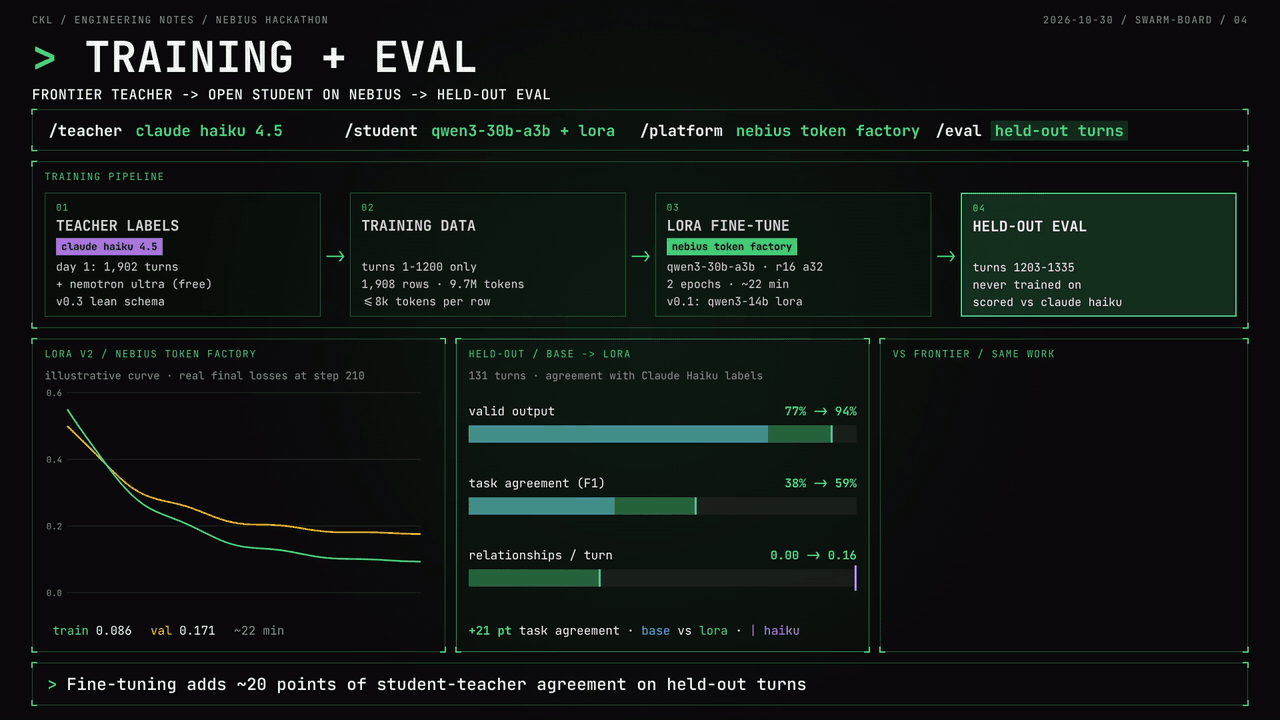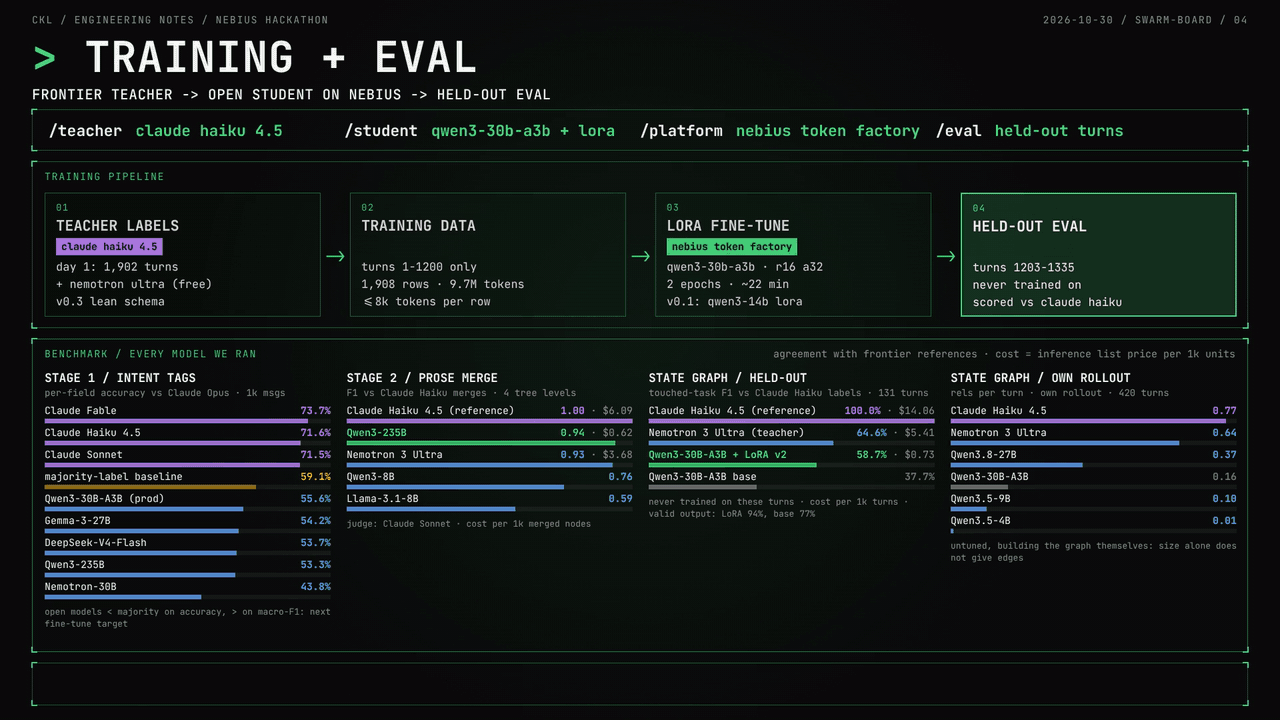
Teacher. Claude Haiku 4.5 (lean schema) labels Day 1 of the gamejam fleet turn by turn; Nemotron 3 Ultra lean labels are added as a second teacher (v1: Haiku 4.5 lean 1001 + Nemotron Ultra lean 652; v2: Haiku 4.5 lean + Nemotron Ultra lean (8k-fit ladder)).

Student. Qwen3-30B-A3B with a LoRA adapter (rank 16, alpha 32, up to 8128 tokens per row), trained on Nebius Token Factory: v1 ~16 min, 1653 rows, 1 epoch · v2 ~22 min, 1908 rows, 2 epochs.

Held-out eval. Later Day 1 turns the adapter never saw, scored against the Haiku labels with the same exported prompts for every arm. Full numbers: eval · State graph.
Training and eval: teacher labels, training data, LoRA fine-tune, held-out eval
Machine reference and human reviews remain separate.
Generated draft turns
1902 / 1902

2026-10-10T14:15:25.380000+00:00 → 2026-10-11T14:15:25.380000+00:00 · generated

Contiguous reviewed turns
0

Export stops at the first unreviewed or rejected turn so earlier state stays trustworthy.

Training jobs run
2

LoRA on Nebius Token Factory, launched outside this dashboard

LoRA training jobs

versionbaseproviderminutesrowsepochsranktrain / val lossserved as
v1 (superseded)Qwen3-30B-A3B-Instruct-2507Nebius Token Factory~1616531160.105 / 0.19lora-mt1 (Modal H100 bf16)
v2Qwen3-30B-A3B-Instruct-2507Nebius Token Factory~2219082160.086 / 0.171lora-mt2 (Modal H100 bf16)

Teachers: v1: Haiku 4.5 lean 1001 + Nemotron Ultra lean 652 · v2: Haiku 4.5 lean + Nemotron Ultra lean (8k-fit ladder). Eval results: eval page.

Human-reviewed export

Day 1 is the machine teacher baseline. Machine-label export is available below; rollout evaluation is being prepared separately. The existing reviewed export requires human-reviewed turns.

Review turns in order, starting with turn #1. The exporter replays your corrections, builds causal context, then splits chronologically with a two-turn gap. At least ten reviewed turns are required to prepare a train/validation split; that is a tooling threshold, not evidence of sufficient training data.

CCT_V02_DATASET=haiku45-lean-day1 python3 scripts/v02/export_training.py

Run from the V0.2 worktree. Files stay under data/v02/haiku45-lean-day1/training/. Nothing is uploaded.

Last export: 0 reviewed turns, 0 training examples, 0 validation examples.

Machine teacher baseline export

The designated Luna Day 1 baseline can train a model to imitate its labels. This is separate from human gold. The exporter preserves the recorded input and original prediction, freezes hashes, and creates a temporal split with a two-turn gap. It requires completed Day 1 by default.

CCT_V02_DATASET=day1 python3 scripts/v02/export_machine_teacher.py

Incomplete previews require --allow-incomplete-prefix. No inference, upload or training job is launched. A temporal split inside one Gamejam does not measure cross-project generalization.

Selected run's latest export: No machine teacher export for this run.